The Broadcom acquisition of VMware has set off one of the most consequential partner ecosystem restructurings enterprise IT has seen in years. What began as a pricing model change has evolved into a procurement crisis, a skills reckoning, and an infrastructure strategy inflection point — all arriving simultaneously. Enterprises that built operational muscle around VMware over a decade or more are now discovering that their procurement relationships, service partners, and internal talent assumptions may no longer hold.
The instinct to treat this as a licensing cost problem is understandable but incomplete. Pricing pressure was already dominating infrastructure decisions before Broadcom changed the equation further. The mistake many enterprises are making is letting the software line item drive a decision that is fundamentally about operational continuity, application dependencies, and multi-year migration risk.
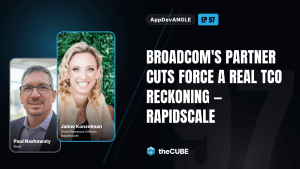
In this episode of AppDevANGLE, I spoke with Jaime Konzelman, Chief Revenue Officer at RapidScale, a managed cloud service provider operating at the center of the VMware disruption, about how enterprises should be thinking through their infrastructure options in the post-Broadcom landscape. Our conversation explored the collapse of the VMware partner ecosystem, why total cost of ownership analysis is more complex than most enterprises realize, the stickiness barriers that make migration harder than pricing frustration alone can overcome, how VCF 9 is blurring the boundary between infrastructure and platform engineering, and what AI-ready infrastructure actually means in practice.
The broader signal here is not that enterprises are abandoning VMware. It is that they are being forced into strategic infrastructure decisions far faster than their planning cycles, skills, and application maps can support. The consequences of getting it wrong are compounding as AI workloads raise the stakes.
The Partner Ecosystem Collapse Created a Procurement Crisis, Not Just a Vendor Problem
When Broadcom consolidated the VMware partner program, the reduction in authorized partners was dramatic. Konzelman noted that the program went from more than four thousand partners down to approximately 126 companies worldwide. That is not a minor vendor list adjustment. It is a structural disruption to how enterprises procure, license, and receive support for one of the most embedded platforms in enterprise infrastructure.
The timing compounds the problem. Three years into this transition, Konzelman observed that enterprises are still regularly encountering the reality mid-conversation: “We talk to enterprises almost weekly who don’t even realize the partner programs have continued to shrink, and the company that they were previously buying their VMware licenses from are no longer part of the program.” The gap between what IT leadership knows and what procurement relationships currently reflect is creating urgency that is not matched by readiness.
This matters because the partner relationship in a VMware environment was never just transactional. Partners provided lifecycle management, licensing guidance, support escalation, and in many cases, operational continuity expertise. Removing that layer without a replacement plan does not simply raise costs, but it also removes institutional knowledge that enterprises did not realize they were relying on. The result is a form of infrastructure risk that does not appear on a budget line item until something breaks.
TCO Analysis for VMware Migration Is Structurally Incomplete at Most Enterprises
The most common framing Konzelman encounters is enterprises comparing their current VMware software invoice to an alternative platform’s licensing cost. That comparison is analytically insufficient, and the gap between a licensing cost comparison and a genuine TCO model is where most migration plans quietly fail.
Konzelman used a pointed analogy from the early public cloud era. Organizations declared they would shut down data centers, eliminate managed services, and run everything faster, cheaper, and better in the cloud, only to find themselves twelve to twenty-four months later with OpEx costs accelerating and operational control diminishing. The parallel to VMware migration is direct. “The software line item is one piece of the equation,” she noted. “What is their actual architecture? What is the infrastructure cost underneath that? When you start to layer on all of those pieces, the actual cost profile — well, now you’re not just comparing the hypervisor layer or the SKU of VMware on your budget line item.”
The full cost picture includes application refactoring expenses, reskilling or backfilling talent that is currently VMware-native, migration project management, performance validation, and what gets lost in operational continuity during the transition. Konzelman pointed out that many VCF customers are using less than thirty percent of the SKUs included in their bundle. The Broadcom consolidation strategy was, in part, designed to change that: creating a public cloud-like experience on private infrastructure, with storage compression, lifecycle management, and application-layer tooling like Tanzu all included. For enterprises that have not yet mapped the full value of what they are already paying for, the migration calculus looks very different once they do.
The implication is straightforward: enterprises conducting VMware migration analysis based primarily on software line-item comparisons are making a three-to-five year operational decision using a one-year budget lens.
Migration Stickiness Is an Application Dependency Problem, Not a Loyalty Problem
Enterprises that dislike what Broadcom has done are not automatically positioned to leave. The barriers are architectural and organizational, not emotional. Konzelman was direct on this point: “Credible VMware migration is an application portfolio program. It’s not simply swapping out the hypervisor layer. Moving a workload is not the same as modernizing it.” Relocating complexity to a different platform does not eliminate the complexity; it displaces it.
This is consistent with broader application modernization research. Our research shows that 40.8% of respondents identified interoperability with other legacy downstream systems as the biggest bottleneck in their modernization pipeline. In a VMware environment, that interconnectedness is deep: networking, security posture, disaster recovery dependencies, and application-level data flows all run through the virtualization layer in ways that are rarely fully documented. The discovery process that precedes a responsible migration is itself a multi-month undertaking before a single workload moves.
Konzelman’s approach at RapidScale reflects this complexity: start with discovery at the workload and application map level, assess data location and network interconnectivity, evaluate security and recoverability, and then sequence migration in waves starting with lower-risk workloads to validate performance and data integrity before touching business-critical systems. The skills question surfaces here as well. If the destination platform is not VMware, the team that currently manages the environment may not have the skills to manage the new one — and that gap needs to be closed before, not after, a workload moves.
VCF 9 Is Collapsing the Boundary Between Infrastructure Operations and Platform Engineering
One of the more structurally significant dynamics emerging from VCF 9 is that the separation between infrastructure teams and platform engineering teams is becoming harder to maintain. Konzelman described enterprises beginning to stand up VCF 9 lab environments specifically to test whether the capabilities can bridge these two historically separate functions: “The folks that are responsible for keeping the lights on, providing the secure environment, with my platform application team who’s really trying to bring new services to market and work at the platform layer — it becomes about more capacity and how do they do that in a repeatable way.”
VCF 9 integrates Spring lifecycle management, Tanzu for container and application orchestration, storage compression, and security scanning in a single bundle. For Java and Spring-based application portfolios, which Konzelman noted now constitute a substantial share of enterprise application estates, this means the same platform managing compute infrastructure can also scan the application environment, automate patching, and support release management. These capabilities were previously siloed across separate tools and teams.
ECI Research data reinforces the visibility gap this creates: 55.2% of respondents indicated only partial visibility into developer productivity metrics, with deployment frequency tracked but lead time or MTTR not consistently measured. Better platform integration does not automatically solve that visibility problem, but it creates the operational conditions under which solving it becomes possible. This is a meaningful distinction for enterprises evaluating whether infrastructure modernization investments will translate to developer outcomes.
AI-Ready Infrastructure Is Raising the Consequences of Infrastructure Decisions Already in Flight
The VMware disruption is not happening in a static environment. Enterprises are making infrastructure platform decisions at precisely the moment that AI workloads are introducing a new set of infrastructure requirements, including GPU utilization, inference cost, data locality, and what Konzelman called the difference between stranded acceleration and productive capacity.
Konzelman’s definition of AI-ready infrastructure was deliberate in its simplicity: “The platform can run production AI securely, economically, and as close to the data being used as possible.” Private cloud environments that already have repeatable provisioning, lifecycle management, and governance in place are better positioned to host AI workloads under those criteria than public cloud environments where token economics and egress costs create compounding spend that is difficult to forecast. The enterprises that have done the platform integration work are better positioned to onboard AI capacity in a controlled, measurable way.
The broader implication, as Konzelman framed it, is that “AI doesn’t eliminate the need for infrastructure decisions. It makes the consequences of those decisions more expensive and a lot more visible.” Organizations that defer the VMware strategy question are not buying time. They are accumulating infrastructure debt at a moment when the cost of that debt is rising.
Analyst Take
The Broadcom-VMware situation has crossed from market disruption into a strategic infrastructure forcing function. The partner ecosystem collapse, pricing escalation, and the emergence of VCF 9 as a platform-engineering-adjacent product are not separate stories. They are pressure points converging on enterprises that have not completed a credible infrastructure strategy review. The traditional approach of managing VMware as a stable, long-cycle infrastructure investment with a stable partner ecosystem no longer describes reality.
What enterprises need to recognize is that the decision before them is not primarily a vendor decision. It is an application portfolio decision, a talent decision, and an AI-readiness decision that happen to have infrastructure at their center. Organizations treating this as a procurement problem are likely to discover that the migration cost and operational disruption dwarf the licensing savings within two years.
The risks here are real and underappreciated. Most enterprise IT organizations do not have a complete application dependency map for their VMware estate. Most lack the skills to migrate and operate a materially different platform without a managed services partner. And most are conducting this evaluation while simultaneously being asked to build AI infrastructure capacity, which is a requirement that rewards organizations with clean, governed, well-instrumented infrastructure environments.
The larger shift is that infrastructure platform decisions that were once measured in refresh cycles are now being measured in AI deployment readiness. The next phase of enterprise infrastructure strategy will be defined less by which hypervisor sits underneath the workload and more by which operational model enables the organization to run production AI securely and economically at scale. Enterprises that use the VMware disruption as a catalyst to build that operational foundation will be structurally advantaged. Those that use it as an excuse to make a fast, reactive platform swap will find themselves having this same conversation again in three years.